Playbook 01
Customer 360 Build
We combined all scattered data of a single ID, including sales, app usage, billing, and support requests, into one profile table to create personalized campaigns for their marketing application.
Recent research shows that most enterprises lose $15 million each year due to poor data quality and engineering practices, which impacts up to 30% of business revenue. Trango Tech, a data engineering agency, addresses these challenges with a modern tech stack that includes pipelines, lakehouses, ETL/ELT, live streaming, and DataOps as part of its data engineering services. All contracts are governed by PRS and transparent, published pricing.
Data engineering services provide behind-the-scenes infrastructure engineering that enables secure data connections between servers and users. Our Data engineers collect, fix, store, live-cast, set security rules for, and monitor data. If the raw data is corrupt, then downstream analysis is useless. Which is why Trango Tech, a data engineering agency, releases every model with a Pipeline Reliability Score, transparent charges $48-$240, data localization, a one-month paid POC on live data, and no training terms in the contract.
Unlike other data engineering service providers that offer data engineering retainers, we offer the four main data engineering solutions where enterprises most often fail, with an above 90 % success rate.
Our team develops automated and independent data engineering solutions that extract raw data, clean it, and automate processes to ensure smooth operations. In the case of incapable systems, we send the data to smart cloud storage and process it there, a process also called ETL development services. Our system is designed to run everything on its own, either by copying data in real time (CDC) or by transmitting it via flexible connectors.
In our data engineering solutions, you get the chance to make your existing data systems fast and modern. We build your system from scratch or improve your cloud database, whether Snowflake, Redshift, or BigQuery. We use globally accepted data table formats, such as Delta or Iceberg, to keep you free from vendor dependent tool traps. We use both traditional and data mesh approaches, as per project needs.
In our live streaming data engineering solutions, we process data in real time pipelines for fraud detection, personalization, IoT assessment, and traceability by using tools like Kafka, Flink, RisingWave, or Materialize. The stateful streaming remembers the accuracy level for perfect results and stamps later arriving data. Altogether, it decides whether your data streaming process works at 99.9% or 99.0% of the time.
We offer DataOps and governance plans for systems that often face downtime; these data engineering services fix flawed data systems in our data engineering solutions services. We use Unity Catalog or Atlan to arrange your data, track its transition, and access plans. And Monte Carlo or Soda to keep a vigilant eye on your processing data; it alerts upon detection with a monthly Pipeline Reliability Score (PRS) system.
Still wondering which of the above data engineering services best aligns with your business goals? Have a 30 minute discovery call in our data engineering consulting services for a clear roadmap.
Often firms enlist 4 to 6 general user cases, but Trango Tech features 12 patterns that define the data engineering services in this tech based world. Each use case below defines the robust architecture, the utilized tech stack, the foundation, and the project completion timelines.
We combined all scattered data of a single ID, including sales, app usage, billing, and support requests, into one profile table to create personalized campaigns for their marketing application.
We developed a data engineering solution that takes raw data, immediately organizes it, uses AI to assess the situation, and makes live decisions while adhering to SOC 2 and PCI DSS laws.
Our supply chain forecasting model for a specific store predicted the location based item demand every week. Resulted in better product handling, either higher demand or lower.
We used stitching ad clicks, web events, and CRM data fusion and identification processes to apply attribution models like Markov, Shapley, or position based for credit allocation.
As data engineering service providers, we captured users' actions, such as clicks and swipes, using the Snowplow platform and saved the results. Later, the tools fix data to show interaction periods.
We developed an intelligent system that gathers information from smart devices, organizes it, and then stores it. The system also downsizes the old data for space optimization and sends alerts.
A healthcare model that collects and organizes patients’ medical information from different sources, and translates the complex terms in simplified form with restricted access for security.
Our big data engineering services include finance and banking GLBA compliant reports. In this case, we ensure data tracking, track AI decisions, performance reports, & update automatically.
Another marketing project in our data engineering consulting services: in this case, we added all advertising costs from 8+ platforms into a single dashboard to provide a clear picture of total time spent.
We used Feast and Tecton feature stores for ML data. This system ensures that AI learns accurately from history, uses correct logic for predictions, and names data point ownership.
We executed the Data Mesh framework to localize data management and organize the system with domain aligned data products, integrated control, and an online customer interface.
We migrated firm data from Hadoop and Teradata standalone systems to cloud based storage, either Iceberg or Delta. The system is gradually transformed to ensure accuracy.
Want to get a complete playbook for any of these use cases? Contact us now! We are data engineering service providers who will send you a budget, a data model, and 3 reasons for product failure in just 24 hours.
We measure our data science engineering services against a 6 dimensional scoring matrix. Unlike other data engineering companies that lack data agreements and pipeline monitoring, we address these by including the Pipeline Reliability Score in the SOW, providing monthly reports, and developing master plans. See below; this is how an efficient production process scores.
Looking forward to completing the PRS rubric and contract articles for data engineering consulting services? Reach us for a full method in contractual language.
There are 5 absolute ways to get big data engineering services for your enterprises; Trango Tech wins in the one column, while the rest reflects real stats. A crucial point where ELT platforms load data into Snowflake for data transformation that enterprises should look for when hiring Data engineering consulting firms.
Already invested in any of these data engineering service providers? Let us know; our data engineering agency will honestly guide you in building, optimizing, or migrating the system.
Often, data engineering companies require a lengthy 45 minute discovery call, but Trango Tech offers a FREE cost estimator for your data engineering solutions. Check the current pricing for data engineering services, and get your personalized estimate after you get in touch.
To build scalable data foundations, we follow a continual improvement approach in our data engineering consulting services. You get high quality data engineering solutions in just 12 weeks via our S.M.A.R.T methodology.
Our data engineering services company starts the process with a 60 minute scoping call. By the end of the call, you will receive a written architectural plan, pricing, and the best match from our senior architect.
Then we design the data engineering solutions that show all connected parts, tool selection, the influenced cost, risk log, and compliance requirements for your model development.
Now we build the first pipeline on your real production data, ensuring safe processing, thoroughly testing to check flawless working, and tracking the data. We only charge the POC fee when you continue.
We conduct stress tests against your messed up previous data, monitor the system, document manual guides, and train your team. The PRS checkpoint is ≥ 90 for production release.
We gradually migrate the model, test both simultaneously for 2 weeks, then slowly shift 25% of users to the new version. The old model is deleted after 30 days if it performs operations smoothly.
Each month, you get the performance report for each pipeline, with cost control setups every 3 months. If lagging is observed below the 85 threshold, we will fix it for free as written in the SOW.
Want to convert this process for your business model? Talk with our Lead Architect. Let’s talk about the real challenges your particular use case may face!
Trango Tech is a reliable AI development company, offering data engineering services in the United States. We showcase 3 commercial models, each following the same 6 phased methodology. It is your choice to choose between a single build, a dedicated pod, or to run and optimize your existing model.
These data science engineering services are ideal for a fixed budget for a particular platform client. A project led by Trango’s senior architect, along with 2 senior data engineers, works with you from the scoping call through the day of deployment. This model is also ideal for enterprises that already have a clear idea of what they want.
We are labeled as the data engineering service providers for offering our dedicated pod data engineering services. In this service, you get a data engineering pod team consisting of 3-5 engineers, including our lead architect, senior data engineers, an analytics engineer, and a DataOps engineer for 3-12 months. This option is best for a build and run setup that’s already growing.
In managed run and optimize big data engineering services, we take ownership of your existing system's health. This service includes performance and incident reporting with overall improvement on a monthly basis. This option is ideal for firms that have already developed a system and are now looking for experts to keep a vigilant eye on their model progress.
Need guidance? We offer data engineering consulting services. Our lead architect will connect with you for 30 minutes and help you find the model that meets your business goals.
Often data engineering companies try to trap you with ‘whatever you’ll pay’, but this is not how it works! Trango Tech offers transparent pricing for data engineering services in the USA, LATAM, CEE, and INDIA with fixed prices as per developer role and the location.
| role × region | USA · onshore | LATAM · nearshore | CEE · E.Europe | India · offshore |
|---|---|---|---|---|
| Lead Data Architect |
$165–$240
/hr
|
$95–$155
/hr
|
$110–$175
/hr
|
$65–$105
/hr
|
| Sr Data Engineer |
$135–$185
/hr
|
$75–$115
/hr
|
$88–$128
/hr
|
$48–$78
/hr
|
| Analytics Engineer |
$115–$145
/hr
|
$65–$95
/hr
|
$78–$108
/hr
|
$42–$65
/hr
|
| DataOps Engineer |
$145–$195
/hr
|
$82–$125
/hr
|
$95–$140
/hr
|
$55–$85
/hr
|
Note: If you select 3+ engineers from 1 region, the rate will be 10-15% lower than the band rate. Specialists premiums: Kafta adds +15%, lakehouse migration +12%, and SR 11-7 regulation +20%. Rates are refreshed every 3 months and last updated on July 2, 2026. Use our ROI calculator below for 12 months number calculation for your use case.
Want to calculate your specific project cost as per your region? Spare just 30 seconds to fill out the form.
Run ROI Calculator$3M / month It is the average pipeline failure rate for large enterprises. As per stats, 4.7 incidents occur every month and take 13 hours to resolve each. Simply, plumbing costs more than your CFOs even realize.
Fivetran Data Pipeline Failures Benchmark, March 2026Around 53% of engineering potential goes into pipeline maintenance rather than building new features. This number alone justifies the need for automated self correction AI systems from day 1.
Fevetran Benchmark + Linkedin data eng activity Q1 2026It is estimated that the data engineering services will cross $95.4B (2026) and reach $167.8B by 2029 at a 11.9% annual growth rate. In short, the demand is increasing with time not stabilizing.
Industry market sizing . Complere Infosystem, 2026As per recent guides, the cost to hire a US data engineer from junior to senior level costs around $160k-$290k in the first year. The rest pays salary, payroll, tooling, recruiting, and other benefits, which is misleading.
KORE1 Cost to Hire Data Engineer 2026 Guide97% of senior data leaders conclude that pipeline failures are the biggest reason behind the slowdown of AI projects and analytics. The plumbing is considered the blockage for a smooth data org.
Fivetran 2026 Data Leader Survey, N=412Lakehouse, Iceberg, and Delta are usually used as a default architectural pattern. Major platforms like Databricks, Snowflake, and Microsoft Fabric are also used as an open table format to keep you free of vendor lock-in.
Bain . Databricks DAIS 2026 industry analysisThe three architectural layers for data engineer consultancy include the source system, Lakehouse, and Activation. Runs smoothly on all modern platforms, defining where the data belongs, how it is governed, and how it works.
At this level, the data is collected from OLTP databases, SaaS apps, IoT, documents, and event streams. Move info instantly upon urgency or may delay the system for scheduled batches. The challenges occurring in the layer involve schema drift and rate limits.
The layer involves data storage in either Iceberg or Delta, transformed in dbt or SWLMesh, engineered in Dagster or Airflow, recorded in Unity or Horizon, and observed in Monte Carlo or Soda. Either you win the data engineering here or lose the plot.
Modern data is fed into the system for actionable value in different ways: BI dashboards, push cleaned data into centralized systems (Salesforce/HubSpot), ML feature stores, fix into vector databases, and AI assistance via MCP. The final user decides data reliability.
Google and you’ll find a tech tools list added on firms' service pages. Trango Tech is the only data engineering agency in the United States of America disclosing the tool stack used at each level of the process, covering from ingestion to modeling.
Ingestion involves information gathering from various systems into your data warehouse or lake. We use CDC for OLTP duplication, batch moves data in bulk, and events for the rest.
The transformation layer involves the shaping of raw tables into modeled, tested, and written data products. This tier is owned by either the analytics or data engineering team.
The steps involve the tools usage where the computer and storage live and run. A data warehouse (analytical database) is a place of data transformation and dashboard queries.
The lakehouse is an open storage layer of our data engineering services company. The use of ACID transforms basic files into sound databases, free from locked in vendor issues.
An important layer, where tables get owned, lineage gets traced, and access permissions are defined. At the catalog and governance level, either the audit passes or fails.
At this stage of big data engineering services pipelines are scheduled, categorized, and organized as software.
For monitoring of data quality, freshness, lineage, and cost, the following tools are used. The system highlights alerts before any human.
Open Source: We choose open source when pipelines are below 20 or your team wants platform ownership. Select Managed / SaaS when time to value holds more importance than internal ownership and Cloud Native when you are depending on a sole provider. Before quoting, we will give you a clear picture of your model requirements.
Want a personalized tool stack report for your case? The selection of tools, alternatives, and reasoning is dependent on your provision, team, and limitations.
Meeting the regulatory compliance requirements and expectations is the most crucial step, where up to 58% of firms fail. Luckily, Trango Tech is a data engineering services company that complies with all applicable industry laws and regulations across the finance, healthcare, retail, IoT, education, energy, and public sectors.
| Industry | Main Laws | Data Localization | Audit Frequency | Hidden Risks | Trango Fit |
|---|---|---|---|---|---|
| Financial services | SR 11-7, GLBA, SOX, NYDFS part 500, & PCI DSS (cards) | Onshore US Cloud and FedRAMP cooperated | SOC 2 yearly and risk review every 3 months | To check ML build require static data records not shifted queries | Strong (40+ engagements) |
| Healthcare / Life Science | HIPAA, HITECH, 21 CFR, & clinical Part 11 | BAA and PHI | HIPAA yearly and pentest biannual | HL7v2 to FHIR R4 translation requires handling terminology drift | Strong (25+ engagements) |
| Retail / eCommerce | PCI DSS, CCPA, CPRA, state privacy laws | Multiple region OK and PII tokenization | PCI scan every 3 month & ROC annually | Credit card info spreads with time so CDE isolation is crucial | Strong (30+ engagements) |
| Manufacturing / IoT | Defense ITAR, CMMC L2/L3, and export controls | ITAR & CMMC for US residents | CMMC annually and continuous access audits | Engineer residency & data centre location must align | Partial (ITAR only for US pod) |
| Government / Public Sector | FedRAMP moderate/high, FISMA, &StateRAMP | FedRAMP access cloud only | FedRAMP annually with ATO renewal | FedRAMP licenses require US citizenship | Partial (via certified partner) |
| Insurance | NAIC Model law, GLBA, & state specific NY DFS or CA | Laws varies with states | NAIC yearly with ad hoc state fillings | State level PII residency for claims data | Strong (12+ engagements) |
| Education / EdTech | FERPA, K-12 COPPA, & state student data laws | K-12 for data residency | FERPA automated audits yearly | Student PII while building is violation | Strong (8+ engagements) |
| Energy / Utilities | Huge power of NERC CIP, FERC, and state PUC | OT/IT separate from control system data isolation | NERC CIP audits every 3 years | OT data needs break to IT lakehouses, use data diodes | Partial (OT/IT bridge work only) |
Want to see the overall status for your specific case? We will send you a one page quick guide addressing the points on how we are the best data engineering service providers for your business.
Combining dealbreakers from approximately 200 of our clients' calls who hired the wrong data engineering agency. We have enlisted 8 risk indicators you should look for when hiring data engineering service providers.
What to check: Insist on seeing any pipeline built for real production. Why it matters: Artificial data hides schema drift, corrupted encoding, and speed restrictions. These are the factors that usually break in production.
What to check: Ask to show SOC 2 Type II report under NDA. Why it matters: SOC Type I is just an outline, whereas Type II has a 12 month operational track record. Anything lower than this will result in system failure.
What to check: Ask for a price list and regular related projects. Why it matters: Data engineering firms who don't publish their pricing tiers publicly may try to charge you in a price maximization trap.
What to check: Ask for the cloud region where your data will be processed and stored, and confirm it in writing. Why it matters: Suppliers can process data without your knowledge because they may have offshore engineers.
What to check: Investigate with technical questions like how they deal with schema evolution on Apache Iceberg. Why it matters: If you receive general answers, such as they use Delta, it means they are behind the times.
What to check: Know the builder's gonna engineer your data. Why it matters: If you don’t get the name of the lead architect, they will probably hire 3 senior freelance engineers. Now the ownership is out of your hands.
What to check: Ask for a sequential strategy including overlapping timeframes and undo features. Why it matters: Standard 50TB migration takes 20-36 weeks with 1 month multitasking.
What to check: How does your vendor measure the product reliability either a measured target or best effort? Why it matters: Paying in the goodwill won’t fix system failure after deployment. Which is why I always look for contractual PRS or system availability.
Desperate to get the total 20 point best vendor audit checklist? Reach out to us; we will send you a 2 page summary file as part of the proposal.
Often the discovery call ends like a card reading. After reviewing the facts, enterprises determine whether the data engineering consulting services consultant is the best choice for their business. Go through the 6 questions answered below to evaluate your agency's expertise.
Good data engineering service providers talk about how they use this tool for schema testing, detect the errors proactively, separate the corrupted data, and notify the system. Pay close attention if they mention dbt contracts or SQLMesh staged processes.
This team doesn't follow alerting schemes or say that Airbyte handles this headache. No proactive strategy, action or withdrawal plan for detected rows. Note whether they mention source team escalation or not.
Well, both systems offer secure data organization. Choosing between the two depends on whether you use Databricks; then Delta is the right choice for you for speed optimization. Otherwise, Snowflake and Trino go for Iceberg, as both systems handle large datasets.
Preferring Delta Lake over Apache Iceberg on the basis of loyalty and personal feelings. They don’t check if the framework supports their client’s system and try to play where others command. Simply, switching tools without any backup plan is unhealthy for your system.
A good data engineering services company will mention manual guides and lineage tracing. They will discuss strategies that start work from the exact point where the system saved its progress. They will give clear messages to the relevant teams about errors and their fix times.
If the vendor talks about checking logs to trace the error for system handling. Such teams have no active or backup plans to recover the defaulted system, no plans to fix the broken system, and no method to update the user.
We follow step by step methods to track and reduce data pricing, including Snowflake’s QUERY HISTORY and WAREHOUSE METERING HISTORY. Data storage and transfer: all steps are reported monthly. Sprints are optimized every 3 months.
They will probably mention the monitoring of bills. Those teams don’t have a strategic plan, no optimization metrics, and have never experienced any crashes. This supplier might amaze your CFO during development, around month 4.
They will mention the use of the Apache Flink framework, as this strategy processes data in real time. The only thing required is a balance between time and speed. Using this framework, they arrange the data and watermarks to finalize it later.
Inexperienced agencies may say that they handle late arriving data upon arrival. But in reality, such data should be watermarked and held to know when to finalize results. It is the most common issue in data engineering; if they cannot answer, it means they have never shipped.
A reputable data engineering consulting service won’t hesitate to talk about past failures and what they learned from them. They can mention gaps that delayed processing or caused inconsistencies due to a transfer bug, Snowflake scaling error, or CDC replay.
They will probably show them as an expert who has never faced any failures. They may blame the clients because, due to unforeseen changes, they couldn't ship it. Indeed, this is not what you are looking for in the SOW.
Curious to learn about the complete 20 vendor evaluation checks? We will send you a spreadsheet vendor comparison matrix for better understanding and decision making.
Big data engineering services address manual data activities, pipeline failures, and outdated information, all of which have real dollar costs. This calculator will count both current status and Trango engagement, particularly for your team, the platform spend, and defect frequency. Get the 12 month ROI calculation right after entering your contact information.
Around 88% of data engineering firms do not clearly mention their regional coverage, but we prioritize compliance and overlap in the US, LATAM, CEE, and India. For the cost of each area's service, please see our published rate matrix above.
| Region | Overlap w/US Eastern | Compliance Fit | Data Control Posture | Best For |
|---|---|---|---|---|
| USA (Onshore) | 1 day | SR 11-7, HIPAA, FebRAMP, ITAR, & CMMC L2/L3 | US data localization and US citizenship pod | Finance, defense, & healthcare sectors with firm residency |
| LATAM (Nearshore) | 5-7 hours/day | SOC 2, Brazil LGPD, PCI DSS, standard US contract | Machine readable data and standard legal contracts via Mexico, Colombia, and Brazil bodies | Live collaboration, daily meetings, economical SOC 2 work, Spanish or Portuguese native product |
| CEE (Eastern Europe) | 3-5 hours/day | GDPR, ISO 27001, & EU AI Act | EU data residency and robust data protection systems | GDPR compliance and research based products, complex engines in Poland & Romania, & avoid operations in Ukraine |
| India (Offshore) | 1-3 hours/day | DPDP Act 2023, SOC 2, & GDPR | Localized data handling requires DPAs and SCCs for EU and US data | Heavy data engineering, rate sensitive scale, 24/7 support, & bulk data workflows |
How we route: The need to meet regional compliance is far more important than cost plans. We neither insist on nearshore if onshore is the demand, nor do we overlap for less than 3 hours a day unless the product is completely out of synchronization. Check our compliance by industry table above to see how we tackle each industry specific regulation requirement.
We asked our last 6 clients why they chose Trango Tech as their data engineering service provider over an internal team, Big 4 consulting, remote staffing, or managed service providers. We have written below their comments along with the title and use case. Identities are hidden for privacy concerns.
The Trango Tech PRS scorecard made the difference. Every other vendor discussed reliability, but they showed us the 6 axis scoring card, which made the difference. Not just spitting what's better, but they follow strategies that will be used to make that difference, as mentioned in the SOW as well.
I already spent $180k on a Big 4 engagement, which just presented me with 40 page slides with no working pipeline. But after the discovery call with Trango Tech, I returned with a written architect report, the budget plan, and affirmation that my case suitability is just 60 minutes.
It was the only data engineering agency that answered my query correctly. I asked them the same question as I asked other firms: where they would process my data. Most agencies said it depends on their engineers' location, but only Trango Tech named the specific region and also mentioned it in the SOW.
The main reason we chose them was a 1 Month paid POC on my real production. Every other firm wanted us to sign the MSA before writing a single line of code, but Trango released operational CPC pipelines in just 3 weeks and gave us the option to investigate before hiring us.
The best thing I found was talking with the same person who is supposed to handle my data. Their lead architect entertained us from the first to the last call, not any sales or account manager. This is how I was sure to get what I actually wanted because of zero communication barriers.
We hired another team earlier, who said to migrate 40TB of data and shipped 11 months later. Then I came across Trango Tech; they said it would take 20-28 weeks in a phased plan in the scoping call, and it literally happened. Cheers to their honesty and proficiency.
Get the names under NDA. Our agent will connect you with the speaker on a discovery call.
Big data engineering services are not sold to everyone. We have highlighted four plots where Trango’s engagement is not the best choice for you. We have also suggested what service you should use as an alternative.
In case you have data and are looking for a model that predicts accordingly, then model development is the right choice for you. It includes feature engineering, model training, evaluation, and deployment. As different subjects go with different screening.
If you already have an active project in progress, all you need is someone to ask better questions about it, such as statistical analysis, experimentation, and BI dashboards. This is called data science, not data engineering.
If you have a disciplined data infrastructure and you are looking for predictive demands, forecast churn, and risk scores, then the predictive analytics service is the right choice for you. This is another special service with different practice standards.
If you already have an architecture, a platform, and a strategy, and all you need is a senior engineer to work directly with your workflows, you need to hire staff, not build the engagement. In short, you are simply paying for an extra pair of helping hands.
Content: This page is written by Maya Okonkwo (Principal Data Architect with 11 years of data science engineering services experience for financial institutions and healthcare organizations. Expert reviewed by Marcus Bell (Principal, Platform Strategy). The page content is refreshed every 3 months against Fivetran standards, LinkedIn Talent Insights, our own data tracking, and the official papers from Databricks, Snowflake, and dbt Labs. Last refreshed on July 2, 2026.
Rate Matrix: The pricing table is divided into 3 sectors. (1) Our own agreement terms. (2) Requirements of external sources including KORE12026, secondtalent.com, and Signify Technology 2026. (3) Adjustments made based on your specific region's cost of living. The costing bands are updated every 3 months.
PRS Methodology: We follow a 6 dimension PRS methodology, including freshness, completeness, lineage, schema stability, cost efficiency, and observability. Each point is measured monthly on a 0-100 scale via Monte Carlo, Snowflake, Unity Catalog, and monitoring status. Your final score is calculated based on the average of other factors. The full rubric is available on request.
Conflict of Interest: We are not the sellers of Snowflake or Databricks; we have partnered with them, which reflects our technology adoption. The tools' usage shows readiness, and recommendations show our engineering judgment, not partnership commission.
Correction: If you find any errors or areas for improvement, please contact us at [email protected]. We’ll get back to you within 38 hours with an acknowledgment.
Version History: This page was made live on February 8, 2026. Refreshed on April 15, 2026, with cost plans, followed by the addition of tool stacks and compliance and industry matrix on June 22, 2026. Last updated on July 2, 2026, with PRS methodology published publicly and our playbook catalog mentioned. Now, the next scheduled update is in Q4 2026.
See 3 of our past engagements from the last 18 months in the US. Names are covered under NDA, although each client's respective industry, project scope, and the results are discussed below.
We migrated about 8 scattered data marts into a single Iceberg lakehouse on Databricks. All records related to profile activity are gathered on a single customer profile as a master record.
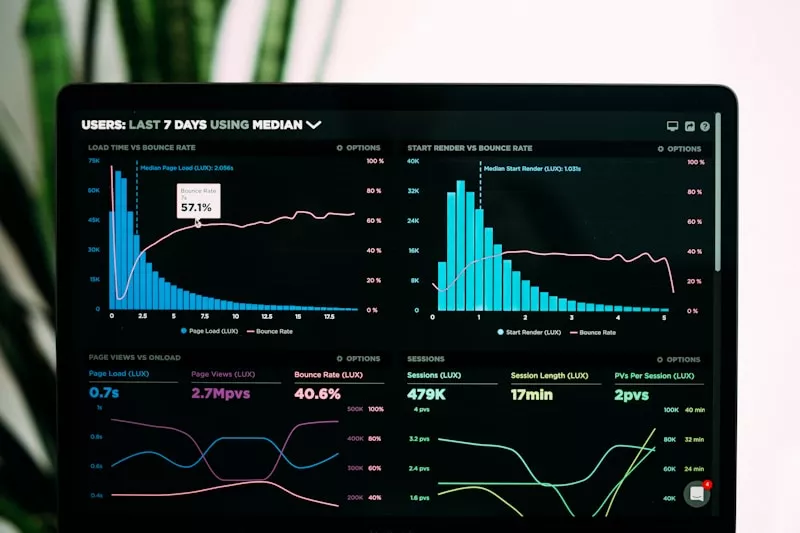
We made an intelligent fraud detector that processes credit card data instantly and transacts securely. It uses the same logic for training, serving, and live forecasting, and replaces numbers with safe tokenization.
We bring the patients' records from 22 hospitals into a single cloud platform and standardize medical terms for all. Each individual can view their own data, as the system is HIPAA compliant.
Most data engineering services seem to appear good by week 4 but show real consequences and system failures by week 24. Mostly, the reasons are the following: neither the vendor nor the framework choice nor the cost plan.
Fivetran’s 2026 standard reports an average pipeline failure rate of 4.7 per month, with each failure taking 13 hours to resolve. This interruption time costs about $3M per month. This issue cannot be addressed by hiring the best engineers; rather, fix the monitoring, lineage, and reliability score from, say, one not after the first downtime.
As per recent industry stats, about 53% of data engineers' time is consumed in fixing pipeline issues. The number says it all: more than half of the time developers are spending is on maintenance rather than building new pipelines. The solution is simple: the data pipelines should be self healing with declarative automation and CDC.
These days, data engineering agencies rely on modern technologies for data automation, storage, processing, and transformation. For open formats and advanced practices, we use tools like Apache Iceberg, dbt, SQLMesh, and Dagster. In 2026, Agentic data engineering is used, which includes Lakeflow and Cortex pipelines. If any firm still uses ETL services, they are simply behind the times.
The total cost for data engineering ranges from $50k to $500k, with 20-30% spent on annual maintenance. Including cloud platform costs, $20k-$200k per year; data migration takes about 30%; tooling requires about 40%; and monitoring tools fall in the range of $30k-$80k per year. Use our ROI calculator to get the real value of your data.
About 98% of data engineering agencies claim to have senior architects and engineers. The main question is: what if they are not a perfect fit for your project? We have clearly mentioned a 5-day replacement option in our SOW. Before you fully invest in our service, we offer a 4-week paid POC for your scattered production data. See how that compares to internal, Big 4, offshore, and other vendor-based offerings.
If you are unable to find answers to your queries, then give us a call. We will be happy to assist you.
Data engineering services are like plumbing and system operations. It collects data from various platforms, cleans the data, organizes it, and stores it securely so it can be used later for smooth business operations and AI-based applications for quick decision-making. If any dashboard or machine learning is dead or hurt, troubleshooting typically starts from here. Check our 3 layer architecture explainer above.
The range is wide depending on your project scope. A single pipeline build typically falls in the range of $45k-$120k. Building from scratch ranges from $180k to $650k; the data migration ranges from $400k to $1.4M; the maintenance facility costs about $14k per month. You can use our cost estimator for your specific use case.
We follow a 6 phase delivery timeframe to develop data pipelines. It typically takes 2-6 weeks to develop a unique source CDC pipeline into a lakehouse. 4-8 weeks to build an automated data pipeline that includes raw data transformation via dbt, the migration, and the monitoring. The lakehouse transition takes 12-20 weeks, and enterprise migration takes 20-36 weeks.
Our PRS methodology includes 6 points, including freshness, completeness, lineage coverage, schema stability, cost efficiency, and observability. Each metric is measured out of 100; the final pipeline reliability score is obtained as the average of all factor scores. We have committed to achieving at least an 85% PRS score with a 90% production success rate for our data engineering services. See the PRS section above.
No, we don’t train any of our AI and ML models using your model data. It is also mentioned in our SOW that we do not even use your model data for our own research. Also, we have turned off access in the Cloud providers' settings; no one can use your data to train their AI models.
Below, we have used simple wording to make it easy for you to understand the technical terms used above.
Pick the most suitable option for data engineering consulting. We will connect you with our senior data architect, not a sales representative.
In the project discovery call, we offer a written architecture document, the costing plan, and service suitability with yes/no. No sales calls or follow ups!
To find the cost, we ask you five simple 5 questions that take 90 seconds to answer. We will reveal the costing plan, team structure, project timeline, and contact details.
Run EstimatorWe send full published pricing modules, PRS rubric, and SOW clauses directly to the email address you provided; no verbal information is shared.
Trango Tech . 1923 Washington Ave, Houston, TX 77007 . +1 (866) 846-5679 . [email protected]